Quick Tour of svy-sae: Small Area Estimation in Python

Fay–Herriot, BHF, and EBP models on three classic datasets

Tutorials
Overview
Python
A five-minute tour of svy-sae for small area estimation in Python: a Fay-Herriot model of milk expenditure, a BHF model of county crop areas, and EBP poverty indicators, with the results API.
Author

Mamadou S. Diallo, Ph.D.

Modified

November 8, 2026

Keywords

small area estimation Python, svy-sae quick tour, Fay-Herriot Python, EBLUP Python, EBP poverty indicators

WarningAbout these examples

This tutorial illustrates the svy-sae API; it is not a rigorous small area analysis. The models are kept simple so each step stays readable, and in many places, from the choice of covariates to the variance model, better choices could be made to improve them.

A five-minute, hands-on tour of svy-sae: an area-level model, a unit-level model, and poverty indicators, each on a classic small area dataset that loads with svy.datasets. Each section links to a deeper tutorial, where every step runs on one realistic survey.

Which model?

The model follows from the data you have:

Table 1: Choosing a model
You have Fit Tutorial
One row per area: a direct estimate, its sampling variance, and covariates AreaLevel.fh() Fay–Herriot
Survey records and the population’s covariate means by area UnitLevel.eblup() BHF (EBLUP)
Survey records and the population’s records, for poverty and other nonlinear indicators UnitLevel.ebp() Molina–Rao (EBP)

Starting from survey microdata and want area-level inputs? Compute the direct estimates with svy first: see Preparing inputs.

Area level: milk expenditure

The milk data hold direct estimates of average household expenditure on milk for 43 small areas, with their sampling variances and four major areas:

import polars as pl
import svy

import svy_sae as sae

milk = svy.datasets.load("milk").data

milk.head()
shape: (5, 7)
SmallArea ni yi SD CV MajorArea variance
str i64 f64 f64 f64 str f64
"1" 191 1.099 0.163 0.148 "1" 0.026569
"2" 633 1.075 0.08 0.074 "1" 0.0064
"3" 597 1.105 0.083 0.075 "1" 0.006889
"4" 221 0.628 0.109 0.174 "1" 0.011881
"5" 195 0.753 0.119 0.158 "1" 0.014161

AreaLevel takes the area table; fh() fits the Fay–Herriot model, here with the major area as a categorical covariate:

fit = sae.AreaLevel(milk).fh(
    y="yi",
    x=svy.Cat("MajorArea", ref=1),
    variance="variance",
    area="SmallArea",
)

print(fit)
╭──────────── SAE: Fay-Herriot (MSE: Prasad-Rao) - Area Level ─────────────╮
│ Method     REML  Log Likelihood   12.6775                                │
│ No. Areas    43  AIC             -15.3549                                │
│ No. Obs      43  BIC              -6.5489                                │
│                  KIC             -10.3549                                │
│                                                                          │
│                                                                          │
│  Term          Estimate   Std.Err       z   p-value    [0.025    0.975]  │
│  ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━  │
│  Intercept       0.9682    0.0694   13.96    0.0000    0.8322    1.1041  │
│  MajorArea_2     0.1328    0.1030    1.29    0.1974   -0.0691    0.3347  │
│  MajorArea_3     0.2269    0.0923    2.46    0.0140    0.0460    0.4079  │
│  MajorArea_4    -0.2413    0.0816   -2.96    0.0031   -0.4013   -0.0813  │
│                                                                          │
│                                                                          │
│ Variance components: area variance: 0.0185503 (se 0.007618)              │
│                                                                          │
│ Findings:                                                                │
│ - Area effects not normal                                                │
│ - 2 influential areas                                                    │
╰──────────────────────────────────────────────────────────────────────────╯

The summary closes with the findings: checks svy-sae runs on every fit, here non-normal area effects and two influential areas. The predictions come with their MSE, coefficient of variation, and interval:

fit.to_polars("predictions").head()
shape: (5, 8)
area pred mse cv lci uci indicator in_sample
str f64 f64 f64 f64 f64 str bool
"1" 1.021971 0.01346 0.113524 0.794575 1.249367 "mean" true
"2" 1.047602 0.005373 0.069969 0.903934 1.19127 "mean" true
"3" 1.067951 0.005702 0.070707 0.919949 1.215954 "mean" true
"4" 0.760817 0.008542 0.121477 0.57967 0.941963 "mean" true
"5" 0.846157 0.00958 0.115671 0.654321 1.037993 "mean" true

The MSE is analytical (Prasad–Rao) by default. A parametric bootstrap takes one argument:

fit_boot = sae.AreaLevel(milk).fh(
    y="yi",
    x=svy.Cat("MajorArea", ref=1),
    variance="variance",
    area="SmallArea",
    mse="bootstrap",
    n_reps=500,
    rstate=12345,
)

fit.to_polars("predictions").select(
    "area", "pred", pl.col("mse").alias("prasad_rao")
).join(
    fit_boot.to_polars("predictions").select(
        "area", pl.col("mse").alias("bootstrap")
    ),
    on="area",
).head()
shape: (5, 4)
area pred prasad_rao bootstrap
str f64 f64 f64
"1" 1.021971 0.01346 0.012536
"2" 1.047602 0.005373 0.00544
"3" 1.067951 0.005702 0.005051
"4" 0.760817 0.008542 0.007982
"5" 0.846157 0.00958 0.008921

The predictions are the same, and the two MSEs are within 15% of each other for every area. The area-level tutorials go on to smoothing the variances, choosing covariates, checking the model, transformations, and benchmarking.

Unit level: county crop areas

The corn and soybean data are those of the original BHF paper: hectares of corn in 37 sampled segments of 12 counties, with the number of satellite pixels classified as corn and as soybeans. A second table holds each county’s mean pixel counts over all its segments:

crops = svy.datasets.load("cornsoybean").data
county_means = svy.datasets.load("cornsoybeanmeans").data

county_means.head()
shape: (5, 6)
County CountyName SampSegments PopnSegments CornPix SoyBeansPix
i64 str i64 i64 f64 f64
1 "CerroGordo" 1 545 295.29 189.7
2 "Hamilton" 1 566 300.4 196.65
3 "Worth" 1 394 289.6 205.28
4 "Humboldt" 2 424 290.74 220.22
5 "Franklin" 3 564 318.21 188.06

UnitLevel takes the sampled units; eblup() takes the population means as pop_data, with the number of segments of each county as pop_size:

fit_bhf = sae.UnitLevel(crops).eblup(
    y="CornHec",
    x=["CornPix", "SoyBeansPix"],
    area="County",
    pop_data=county_means,
    pop_size="PopnSegments",
)

print(fit_bhf)
╭───────────── SAE: BHF (EBLUP) - MSE: Analytical - Unit Level ─────────────╮
│ Method     REML  Log Likelihood  -161.0058                                │
│ No. Areas    12  AIC              332.0115                                │
│ No. Obs      37  BIC              340.0661                                │
│                  KIC              337.0115                                │
│                                                                           │
│                                                                           │
│  Term          Estimate   Std.Err       z   p-value     [0.025    0.975]  │
│  ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━  │
│  Intercept      17.9640   30.9745    0.58    0.5619   -42.7461   78.6740  │
│  CornPix         0.3663    0.0650    5.64    0.0000     0.2390    0.4937  │
│  SoyBeansPix    -0.0304    0.0676   -0.45    0.6532    -0.1628    0.1021  │
│                                                                           │
│                                                                           │
│ Variance components: area variance: 63.3145; residual variance: 297.713   │
│                                                                           │
│ Findings:                                                                 │
│ - 2 influential areas                                                     │
╰───────────────────────────────────────────────────────────────────────────╯
fit_bhf.to_polars("predictions").head()
shape: (5, 8)
area pred mse cv lci uci indicator in_sample
i64 f64 f64 f64 f64 f64 str bool
1 122.563657 85.495105 0.075441 104.440798 140.686515 "Mean" true
2 123.515149 85.64866 0.074927 105.376023 141.654275 "Mean" true
3 113.090748 85.004425 0.081526 95.01997 131.161525 "Mean" true
4 115.020759 83.235856 0.079319 97.138957 132.902562 "Mean" true
5 137.196172 72.017007 0.061855 120.563057 153.829288 "Mean" true

The predictions are the county means of corn hectares per segment. See BHF (EBLUP) for the model and Checking unit-level models for its diagnostics.

Poverty indicators: income in Spain

A poverty rate is not linear in income, so the BHF model cannot predict it from covariate means. The EBP simulates the income of every population unit instead. The synthetic Spanish data hold the income of 17,199 sampled people in 52 provinces, and the covariates of 713,301 people in five of them:

income = svy.datasets.load("spain_synth_income").data
population = svy.datasets.load("spain_synth_covariates_oos").data

poverty_line = 0.6 * income["income"].median()

print(f"Poverty line: {poverty_line:,.0f}")
Poverty line: 6,477

The poverty line is 60% of the median income, a common relative line. ebp() takes the population records, the indicators, and the poverty line. Some incomes are negative, down to about −1,600, so transform_shift moves them above zero before the Box–Cox transformation:

fit_ebp = sae.UnitLevel(income).ebp(
    y="income",
    x=[
        "age2",
        "age3",
        "age4",
        "age5",
        "nat1",
        "educ1",
        "educ3",
        "labor1",
        "labor2",
    ],
    area="prov",
    pop_data=population,
    indicators=["headcount", "gap"],
    threshold=poverty_line,
    transform_shift=3600.0,
    n_mc=50,
    n_reps=0,
    rstate=12345,
)

fit_ebp.to_polars("predictions").pivot(
    on="indicator", index="area", values="pred"
)
shape: (5, 3)
area Poverty Gap Poverty Headcount
i64 f64 f64
5 0.05603 0.177049
34 0.079499 0.233159
40 0.09006 0.257252
42 0.070587 0.207253
44 0.095911 0.271725

The model is fitted on all 52 provinces; the predictions cover the five in the population file. n_reps=0 skips the bootstrap MSE, whose replicates are drawn from the population file and so would refit the model on five provinces only. See Molina–Rao (EBP) for the indicators, transformations, custom indicators, and computing time, and Weighted EBP for survey weights.

The results object

Every fit returns an SAEResults. Printing it gives the summary; to_polars() gives each part as a table:

Table 2: Tables of SAEResults
to_polars(...) Content
"predictions" One row per area (and indicator): pred, mse, cv, lci, uci, in_sample
"fixed" Regression coefficients with standard errors and intervals
"components" Variance components
"diagnostics" One row per area: residuals, area effects, Cook’s distance
"units" Unit-level fits: one row per sampled unit
"tests" Normality, R², variance inflation, and other model-level tests
"findings" The checks that failed, with a code, a detail, and a hint
fit.to_polars("findings").select("code", "detail")
shape: (2, 2)
code detail
str str
"SAE_NONNORMAL_AREA_EFFECTS" "Shapiro-Wilk W = 0.878, p = 0.…
"SAE_INFLUENTIAL_AREAS" "Cook's distance above 0.093: […

fit.findings() applies the same rules at other thresholds, and fit.refit() reruns the fit with some arguments changed, such as fit.refit(mse="bootstrap").

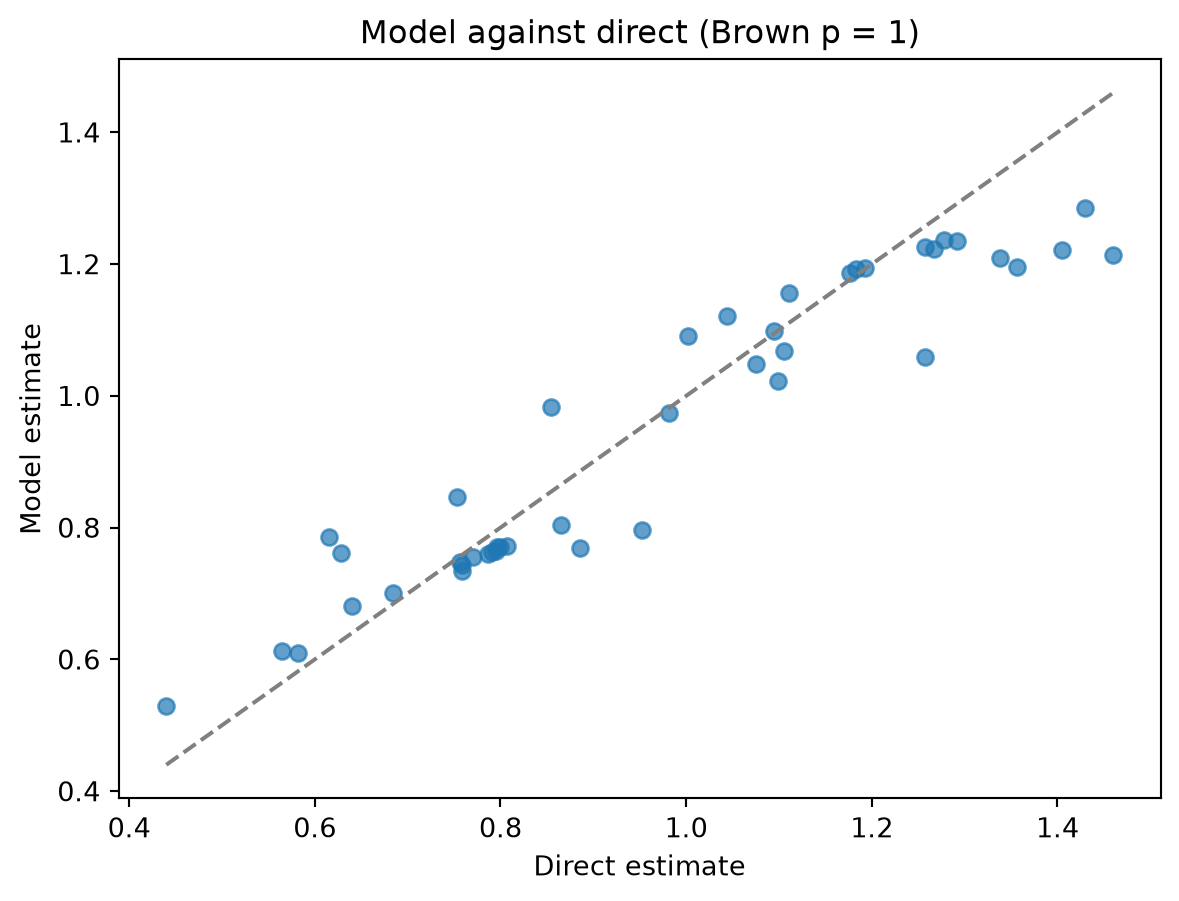
Diagnostic plots hang off .plots:

fit.plots.model_vs_direct();

Direct estimates against Fay–Herriot predictions for the milk data

Key takeaways

✅ Three entry points: AreaLevel.fh() for area tables, UnitLevel.eblup() for means from unit records, UnitLevel.ebp() for poverty and other nonlinear indicators.

✅ Uncertainty with the estimates: MSE, CV, and intervals, analytical or bootstrap.

✅ Checks built in: every fit runs its diagnostics and reports what failed as findings.

✅ Tables out: to_polars() returns every part of a fit as a polars DataFrame.

Next steps

The tutorials take each model step by step on one synthetic household survey, from the direct estimates to diagnostics, transformations, and benchmarking, and check every estimate against the census.
Start the tutorials
Continue to Direct estimates and their limits →